影响与后续:可能影响:相关能力若经后续材料验证,可能改变 3D 场景生成的输入与输出方式;但现有来源不足以判断生成质量、实际适用范围、用户规模或商业影响。 后续观察:应继续核对 Atlas 的公开演示、镜头控制表现、三维数据可用性和使用限制;在新增证据出现前,不应推断其市场采用情况或竞争格局变化。
World Labs, co-founded by AI researcher Fei-Fei Li, has announced Atlas, a world model that generates, reconstructs, and simulates 3D scenes from just a few images. The company claims it beats specialized models at their own tasks, which could make many of them unnecessary.
Since its founding, World Labs has pursued the goal of "spatial intelligence":https://the-decoder.com/fei-fei-lis-world-labs-raises-one-billion-dollars-for-spatial-intelligence/, the idea that AI should understand 3D space the way humans do. Atlas is the company's first model built to do that at scale. Rather than producing flat images or video clips, it grasps how a scene looks from any angle and how it changes over time.
World Labs describes Atlas as an omni-model trained from scratch on text, images, video, and 3D data. Every input gets anchored to a specific position in 3D space rather than processed as a flat sequence. The company calls this shared spatial understanding "spatial context," and it's what the model uses to generate each new frame or viewpoint. According to World Labs, this anchoring separates Atlas from pure language or video models.
Fei-Fei Li laid out this exact problem:https://the-decoder.com/the-scientist-who-taught-ai-to-see-now-wants-it-to-understand-space/ in a November 2025 essay. Current multimodal language models and video diffusion models break data into one- or two-dimensional sequences, she argued, which makes even simple spatial tasks needlessly hard. What's needed are architectures that organize tokenization, context, and memory in a 3D- or 4D-aware way.
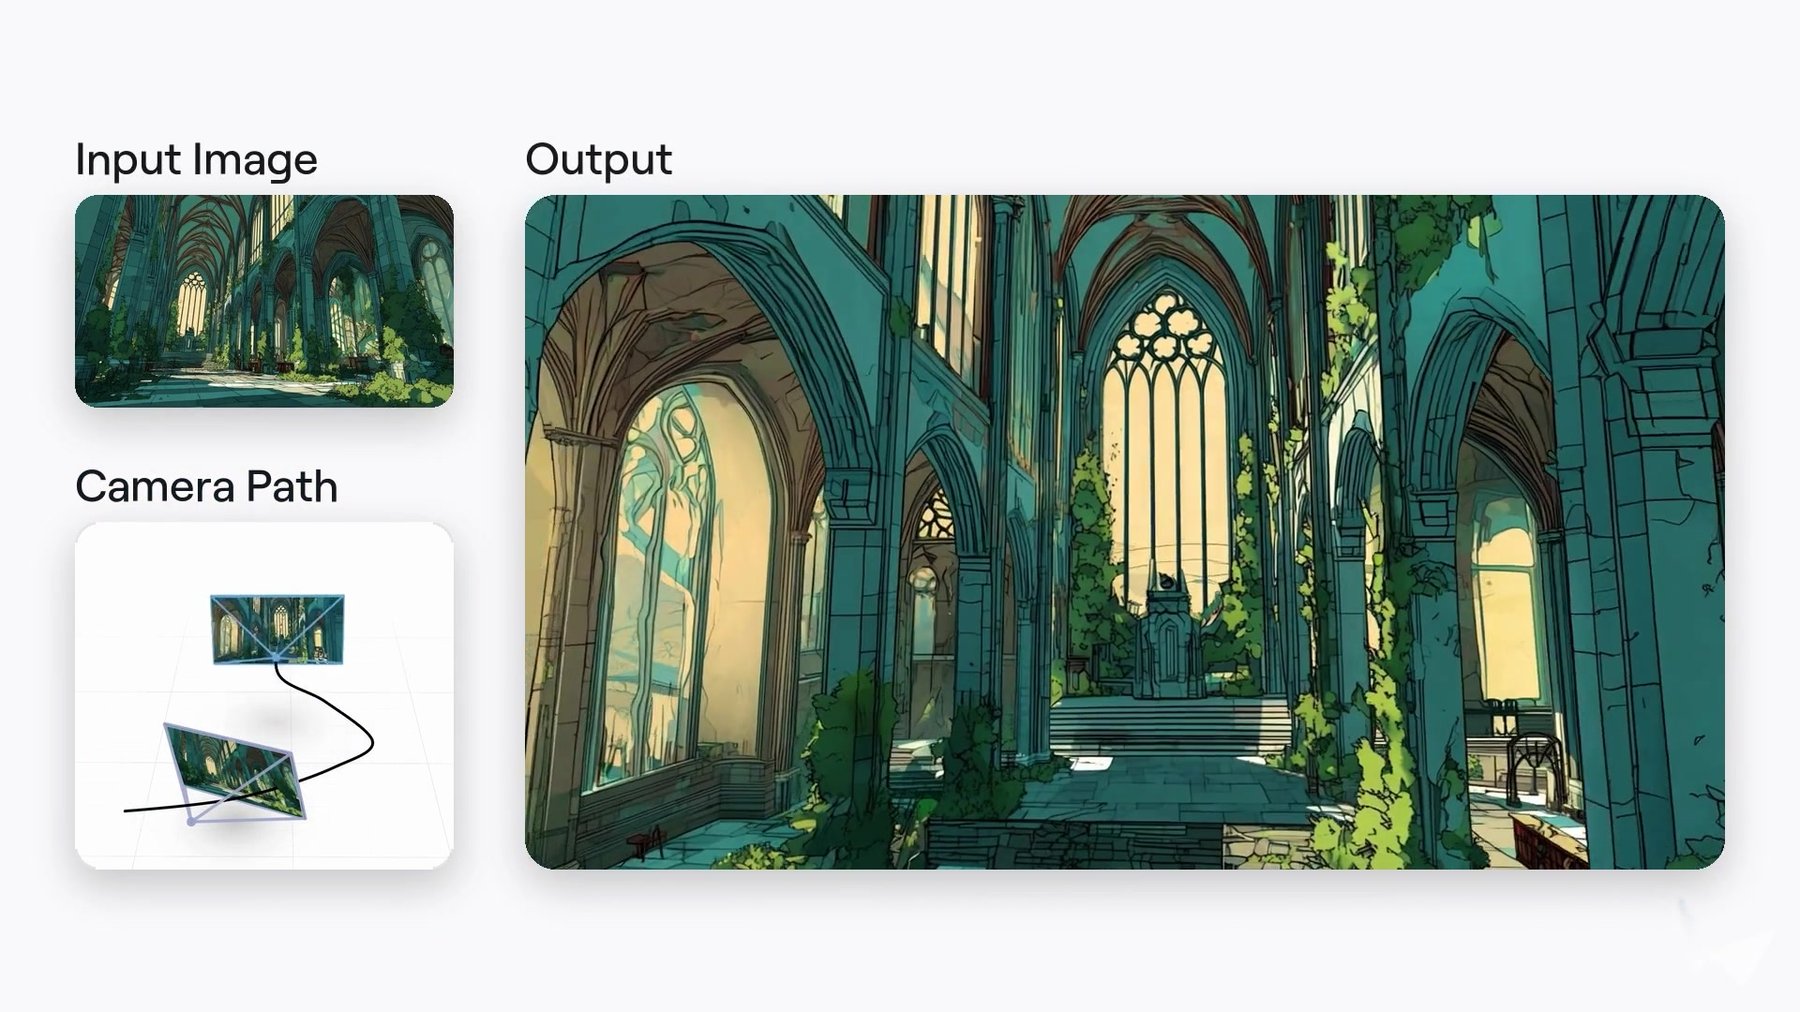
For camera-controlled generation, Atlas takes one or more images and produces new views at freely chosen camera positions and angles. Camera movement is passed as a direct geometric input rather than described through text prompts, as many video models require.
The model outputs up to one minute of video at 1440p. Users can control every shot themselves instead of "pulling the lever on a slot machine," as World Labs put it, drawing a line between controlled generation and random output.
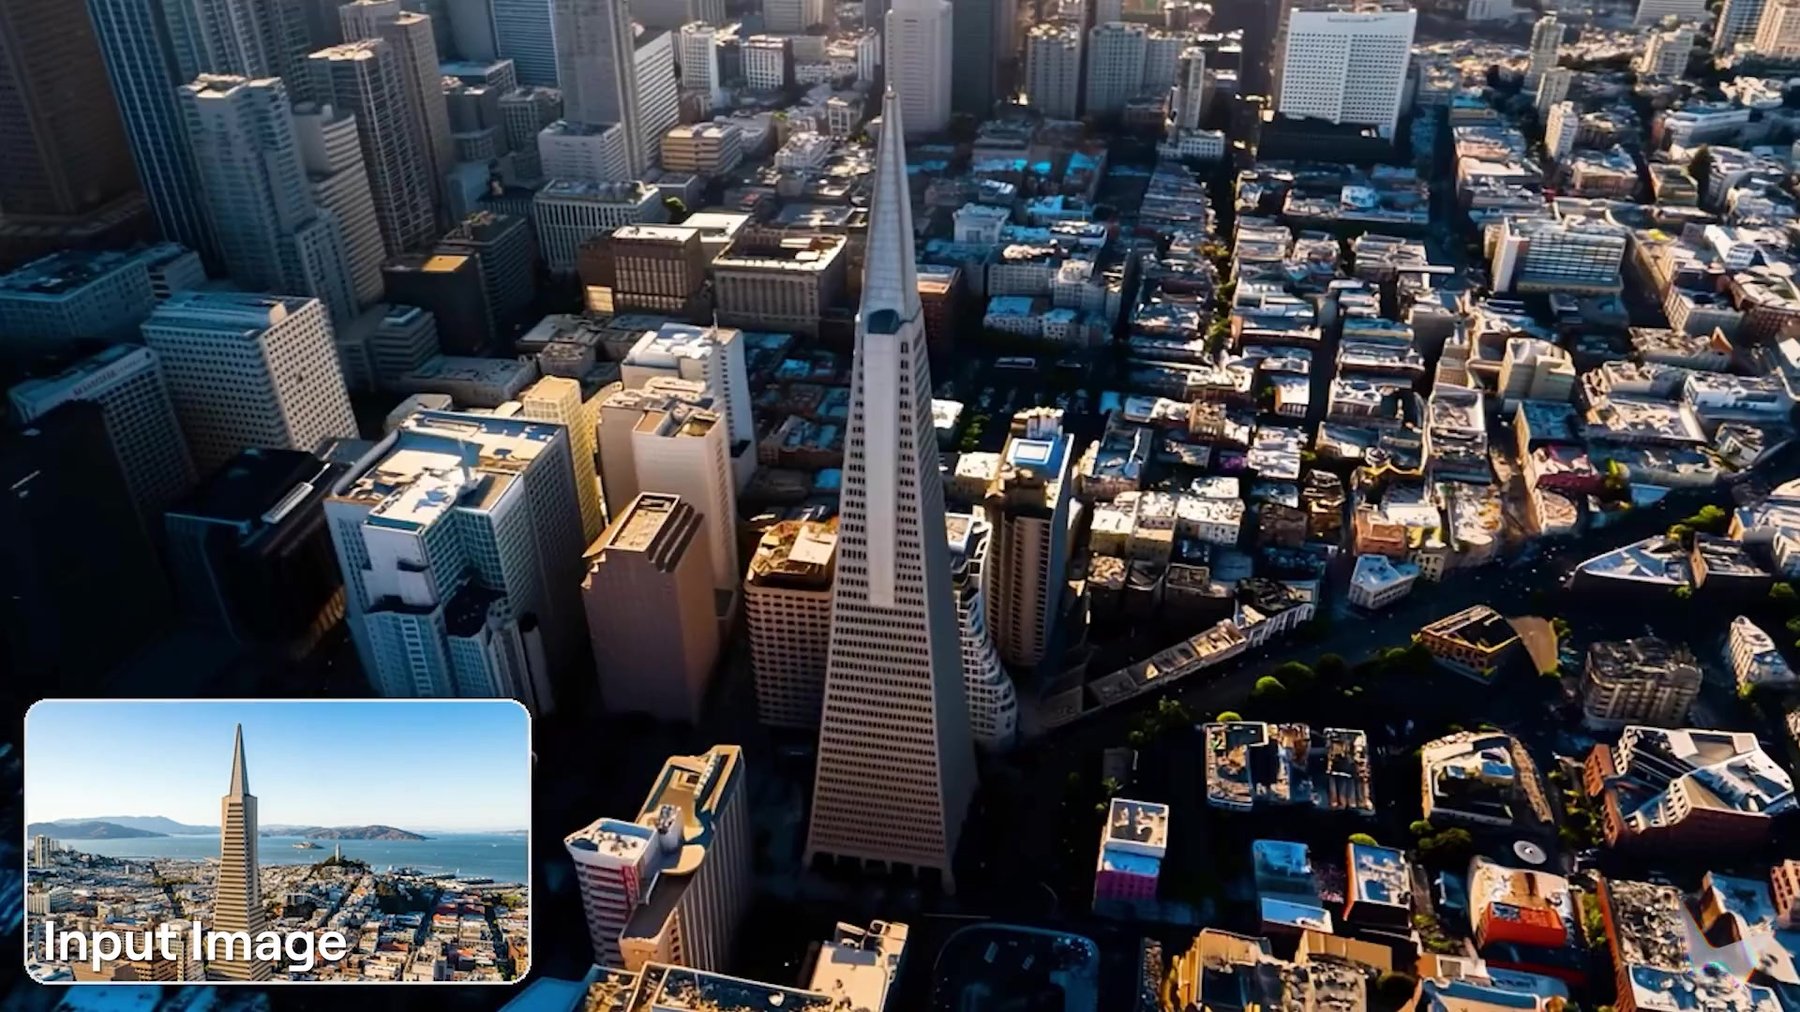
For spatial reconstruction, Atlas rebuilds real scenes from as few as one to several dozen input images without special capture equipment. The more images it receives, the less it has to fill in from its own knowledge.
With just two or three images, Atlas delivers faithful results and outperforms specialized 3D models, according to World Labs. It can also handle over a hundred inputs. In one demo, the model progressively assembles Stanford's Main Quad from two to 25 ground-level photos and generates aerial views far above the campus.
This is where existing models tend to fall apart. In a comparison within the OpenWorldLib framework:https://the-decoder.com/researchers-define-what-counts-as-a-world-model-and-text-to-video-generators-do-not/, systems like VGGT and InfiniteVGGT showed geometric inconsistencies and blurry textures as soon as the camera moved significantly.
Atlas can output results as actual 3D data, not just images or video, because it processes depth information alongside RGB. Supported formats include point clouds and 3D Gaussian splats:https://en.wikipedia.org/wiki/Gaussian_splatting, which build a scene from many small spatial data points that can be viewed smoothly from any angle. This matches the representation used in Marble, the company's existing product:https://the-decoder.com/startup-founded-by-godmother-of-ai-aims-to-give-machines-true-3d-understanding-of-the-world/.
As a simulator, Atlas models space and time together. From footage captured by just a few cameras, it can produce a "bullet time" effect that freezes a scene and lets users view it from otherwise impossible angles. The demo footage was shot with a handful of smartphones and action cameras, not professional gear.
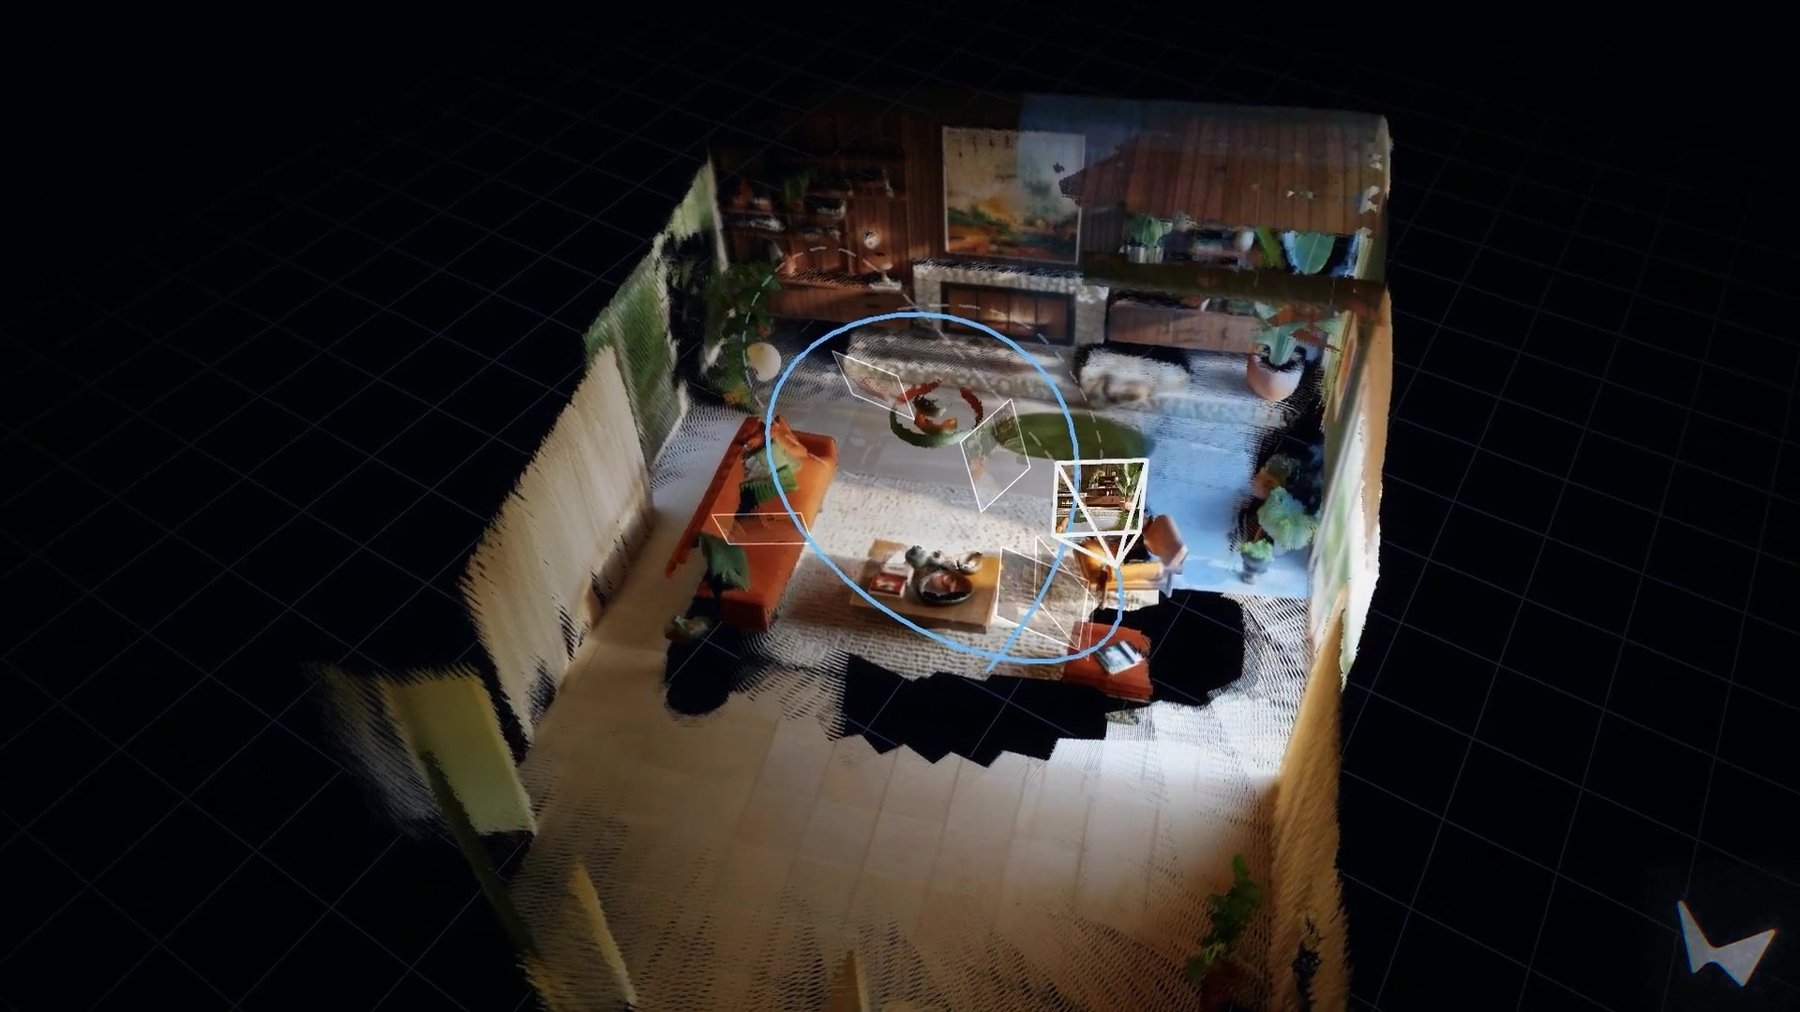
For robotics, Atlas serves as a real-to-sim tool. It reconstructs a room and generates the image and depth data that a simulated robot's sensors would see along its path. From just a few photos, users can simulate and vary grasping and movement tasks by swapping out objects, positions, lighting, or backgrounds. The goal is to produce diverse training data for robots without capturing every situation in the real world.
World Labs showed this approach in August 2026 with its real-to-sim-to-real engine:https://the-decoder.com/world-labs-turns-one-real-world-robot-task-into-thousands-of-simulated-variations-for-training/ as a standalone product. That engine creates thousands of variants from a single real-world task and trains control models entirely in simulation. On five robot platforms, the models ran for an hour each without human intervention, according to the company. The technology came from SceniX, a startup World Labs acquired in July.
Text-to-image generation isn't the main focus, the company says, but Atlas can also follow complex prompts, render text, produce different visual styles, and create 360-degree panoramas.
Atlas combines ideas from both language models and video models. It generates output piece by piece like a language model, so it can use the same speedup techniques, such as KV caching. But it also uses the diffusion principle from image and video models, gradually filtering output out of noise. That side gives it access to methods that shorten the denoising process or boost image quality.
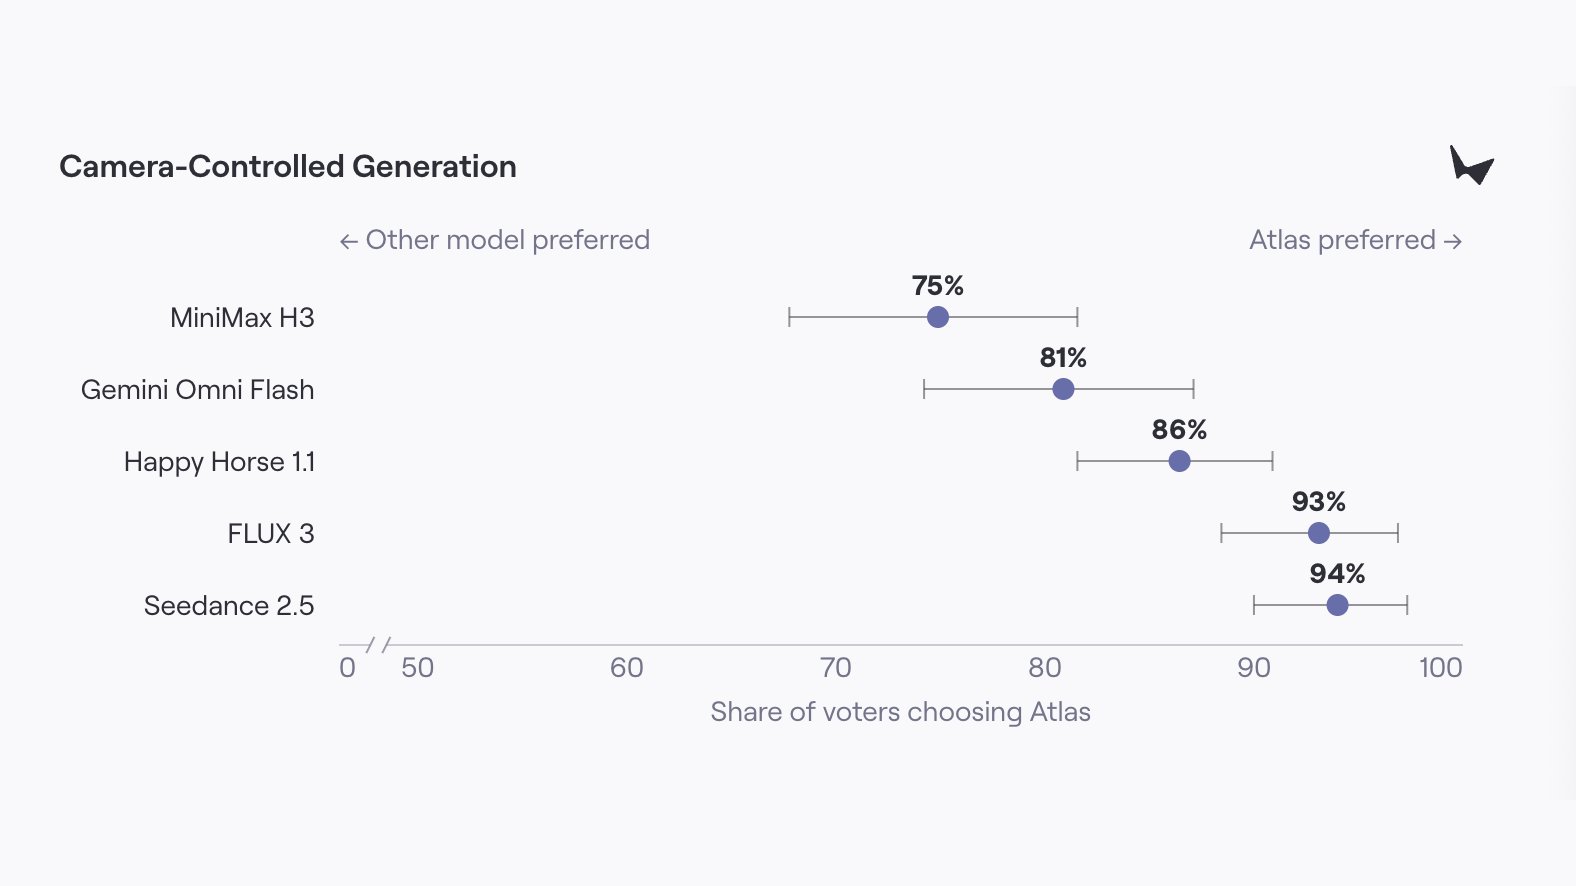
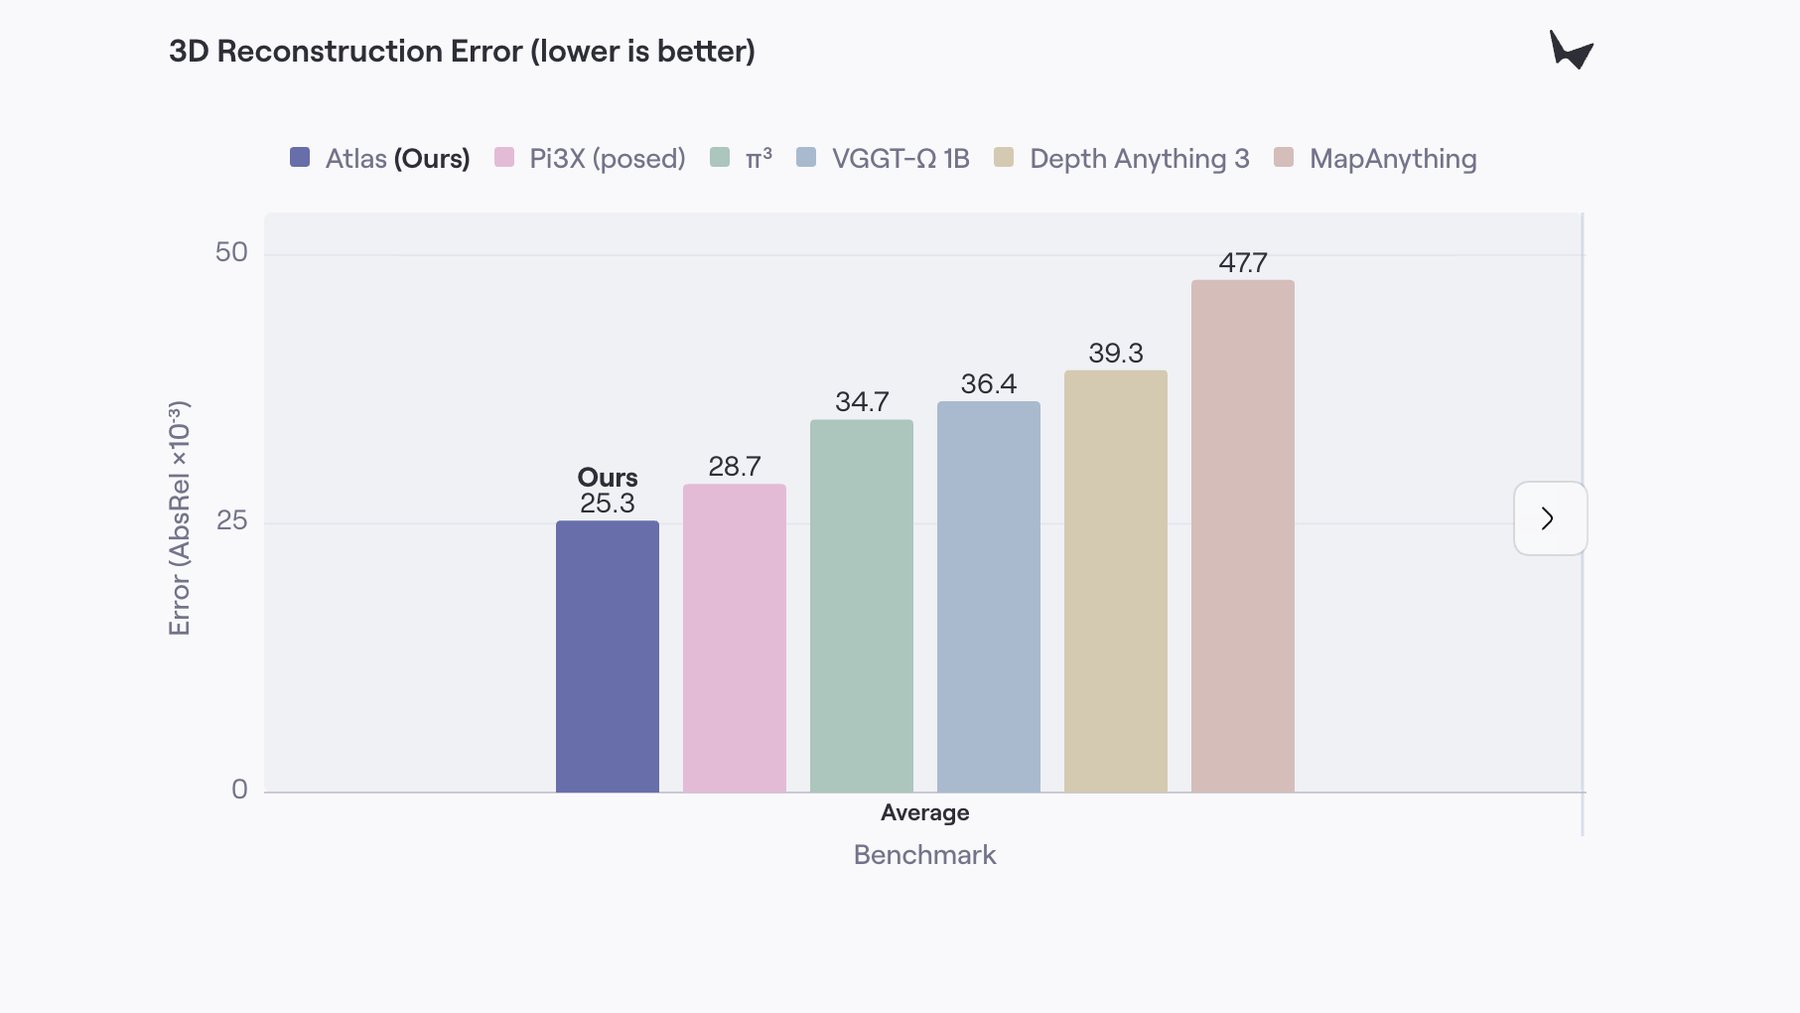
World Labs says no single benchmark captures what Atlas can do, but points to two sets of tests. In camera-controlled generation judged by external human evaluators, and in few-view 3D reconstruction, Atlas outperforms more specialized models.
Human evaluators preferred Atlas in 75 percent of comparisons against MiniMax H3:https://the-decoder.com/chinas-minimax-h3-is-the-first-open-model-to-top-an-ai-video-ranking/?cmpscreencustom=1, 81 percent against Gemini Omni Flash:https://the-decoder.com/googles-gemini-omni-1-1-flash-makes-ai-video-generation-cheaper-and-more-flexible/, 86 percent against Happy Horse 1.1, 93 percent against, and 94 percent against Seedance 2.5:https://the-decoder.com/bytedances-seedance-2-5-generates-30-second-video-clips-with-built-in-audio/. For reconstruction, Atlas leads with a median error of 25.3, ahead of Pi3X and VGGT-Ω 1B.
The company says Atlas's performance improves with more training compute and expects that trend to hold as it scales. Atlas will power future versions of Marble and other products, and is currently available through an early-access program for select partners.
World Labs was founded in 2024 by Fei-Fei Li, who created ImageNet and led Google Cloud's AI division from 2017 to 2018. The company at launch from Andreessen Horowitz, AMD, Intel, and Nvidia.
A first system in late 2024 turned, though users could only move a few virtual meters before hitting invisible boundaries. Marble followed in November 2025. In February 2026 came a $1 billion funding round:https://the-decoder.com/fei-fei-lis-world-labs-raises-one-billion-dollars-for-spatial-intelligence/ from Autodesk, Andreessen Horowitz, Nvidia, and AMD. Bloomberg had previously reported talks at a $5 billion valuation.
What counts as a world model remains contested among researchers. An international team led by Peking University proposed a unified definition:https://the-decoder.com/researchers-define-what-counts-as-a-world-model-and-text-to-video-generators-do-not/ in April 2026 through OpenWorldLib, excluding pure text-to-video models because they lack feedback loops with the real world. 3D reconstruction and simulators like those in Atlas qualify as core building blocks in that framework because they provide environments where physical rules can be verified.
Stay in the loop on AI. Clear, useful, no fluff.
Follow The Decoder for AI news, background stories and expert analyses.
The Decoder:https://the-decoder.com/
情报判断
Aioga 编辑摘要
World Labs 发布世界模型 Atlas,称其可从一张至数十张照片生成、重建并模拟三维场景,并根据用户指定的相机位置和角度生成新视角。模型输出最高可达 1440p、1 分钟视频,也支持点云和 3D Gaussian splats 等三维数据。
背景分析
Atlas 是 World Labs 首个面向规模化空间智能的模型。公司称其从头训练于文本、图像、视频和三维数据,并将输入锚定到三维空间位置。对于场景重建,输入图像越多,模型需要自行补全的内容越少。
Aioga 观点
Aioga 判断:Atlas 的核心差异在于把相机运动作为几何输入,而不是主要依赖文字描述;但目前材料中的性能比较和演示结论均主要来自 World Labs 自述,独立验证信息仍有限。
影响与后续
可能影响:若相关能力在更多场景中稳定成立,三维重建与可控视角生成的工作流程可能被简化;但这不代表专用模型立即失去价值,实际效果、成本和复杂场景表现仍需要进一步验证。 后续观察:应关注 Atlas 的公开可用范围、输入图像限制、输出质量与一致性评测,以及点云和 3D Gaussian splats 等数据能否在真实项目中稳定使用。

 扫码直达文章详情