提示可以累积修补模型弱点的指令。这些指令可能会相对于最新的 Claude 模型功能发生偏移:https://x.com/trq212/status/2080710971228918066。以下是常见的提示“反模式”,它们会削弱前沿 Claude 模型的性能,并可能无意中增加成本:
我们已经在 claude-api 技能中更新了一个新命令,用于注意这些反模式。在 Claude Code 中,对你的提示、技能或工具描述运行 /claude-api prompt-audit。审核会涵盖工作目录中的所有内容,包括调用 Claude API 的应用代码以及 Claude Code 的配置(例如 CLAUDE.md:http://claude.md 或技能)。
例如,我们测试了从 Opus 4.8 到 Opus 5 的模型迁移,在一个客户支持基准测试上开始。我们从一个干净的提示开始,然后逐个植入反模式(一个已弃用的思考设置、一对矛盾的退款规则、一个手动草稿本、“验证两次”、“尽量全面”,以及一项必须的六步程序),共给出六个遗留提示。
我们分别在 Opus 4.8、仅更改模型 ID 的 Opus 5,以及对 Opus 5 每个提示运行一次 /claude-api prompt-audit 后进行测试(图 3 显示了六个提示的平均值)。
图 3 | 从 Opus 4.8 迁移到 Opus 5 过程中提示反模式的影响。
在 Opus 5 中,验证仪式(“验证两次”)在每次退款时重复订单查询,使用了不必要的 token。强调增强器(“尽量全面”)导致数十次不必要的知识库搜索。
运行 /claude-api prompt-audit 删除了反模式,平均降低成本 14.6%,准确率提升 5.3%。成本下降是因为额外的工具调用和重复推理被消除。准确率上升有三方面原因:已弃用的思考设置导致 API 拒绝了所有路由请求;矛盾的退款规则导致 Opus 5 扣留了本应退还的四笔退款,同时要求客户确认;手动草稿本与 Opus 5 内置思考冲突:在三个工单中,它把工具调用写在推理中,但从未执行它。
Effort:https://platform.claude.com/docs/en/build-with-claude/effort 告诉 Claude “努力程度”。在低努力时,Claude 通常会更快得出结论。在高努力情况下,Claude 会进行深入思考、验证并探索其他选项后才回答。
提示缓存、指令和工作量是降低成本的常用手段。我们的文档:https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cut-spend-without-losing-quality 涵盖了更多内容。要对使用 Claude API 的应用代码进行全面的成本审计,我们新增了 /claude-api cost-optimize:它可以分析你的花费去向,应用成本降低措施,并且如果你提供评估,还能显示节省与性能之间的权衡。
cost-optimize 会首先找出你的令牌消耗情况:可以通过你的组织使用情况和成本报告:https://platform.claude.com/docs/en/manage-claude/usage-cost-api(如果你有 Claude 管理员 API 密钥),或从每个 API 响应的 usage 对象获取(如果你的应用记录了它),如果以上都不可用,则通过读取你的请求构建代码并进行估算。
当你已经迁移到前沿 Claude 模型并希望检查现有提示时,请从 /claude-api prompt-audit 开始。它会扫描工作目录中的提示、技能和工具描述。这可以是调用 Claude API 的应用程序代码,也可以是 Claude Code 的配置(CLAUDE.md、skills)。它会去除常见的反模式,这些反模式会阻碍前沿模型的发挥。
当你的应用使用 Claude API 并且希望进行成本审计时,请使用 /claude-api cost-optimize。它会分析令牌使用情况,然后测试各种手段:它会应用提示审计,同时还检查通过提示缓存、批处理未监督工作或限制输出等方式降低成本的可能性。如果你提供评估,它会衡量工作量和模型选择的权衡。
Tuning prompt caching, instructions, and effort can reduce Claude's cost without sacrificing application performance.
Performance and cost are often viewed as a trade-off: to spend less, you accept worse results. In practice, we've found that many applications using Claude Platform can cut costs without giving up performance with three fixes: maximize the prompt cache hit rate, remove anti-patterns from your prompts when upgrading to frontier Claude models, and calibrate effort to the task. We've put this guidance into the claude-api skill:https://github.com/anthropics/skills/tree/main/skills/claude-api. In this article, we show how Claude Code with the claude-api skill can often find ways to reduce cost while maintaining or improving performance.
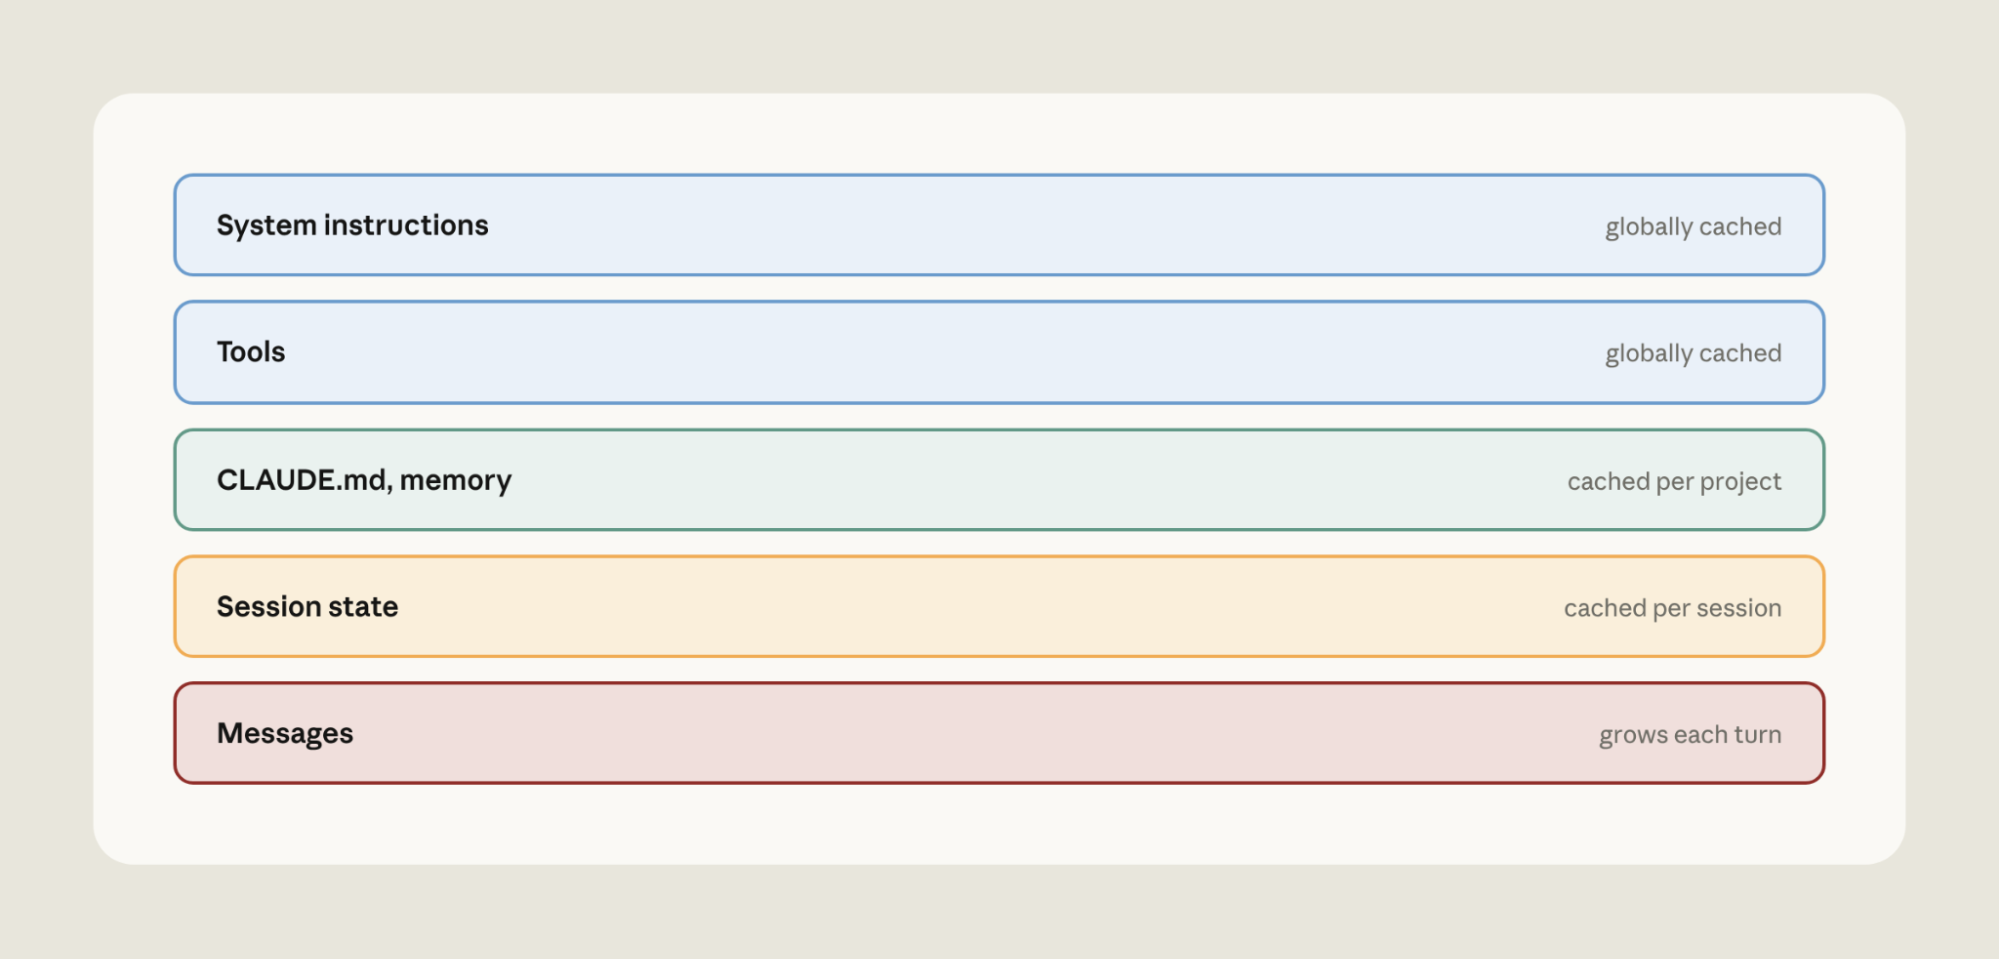
Before Claude generates a response, it first processes your prompt into an internal working state. This step, called prefill , is the expensive part of handling input. Prompt caching saves that state (the key–value, or KV, cache): when a request starts with the same prefix, Claude reads it back instead of recomputing it. Cache reads are billed at a fraction:https://platform.claude.com/docs/en/about-claude/pricing of the full input price.
There are a few practical considerations to ensure effective use of the prompt cache. First, the prompt cache is pinned to a specific model. Second, prompt cache reads must be byte-exact across the prompt prefix. Finally, the prompt cache has a limited time-to-live:https://platform.claude.com/docs/en/build-with-claude/prompt-caching#ttl-support (TTL).
With these points in mind, there are a few practical tips:
We’ve accumulated:https://claude.com/blog/lessons-from-building-claude-code-prompt-caching-is-everything a few lessons for prompt cache management:
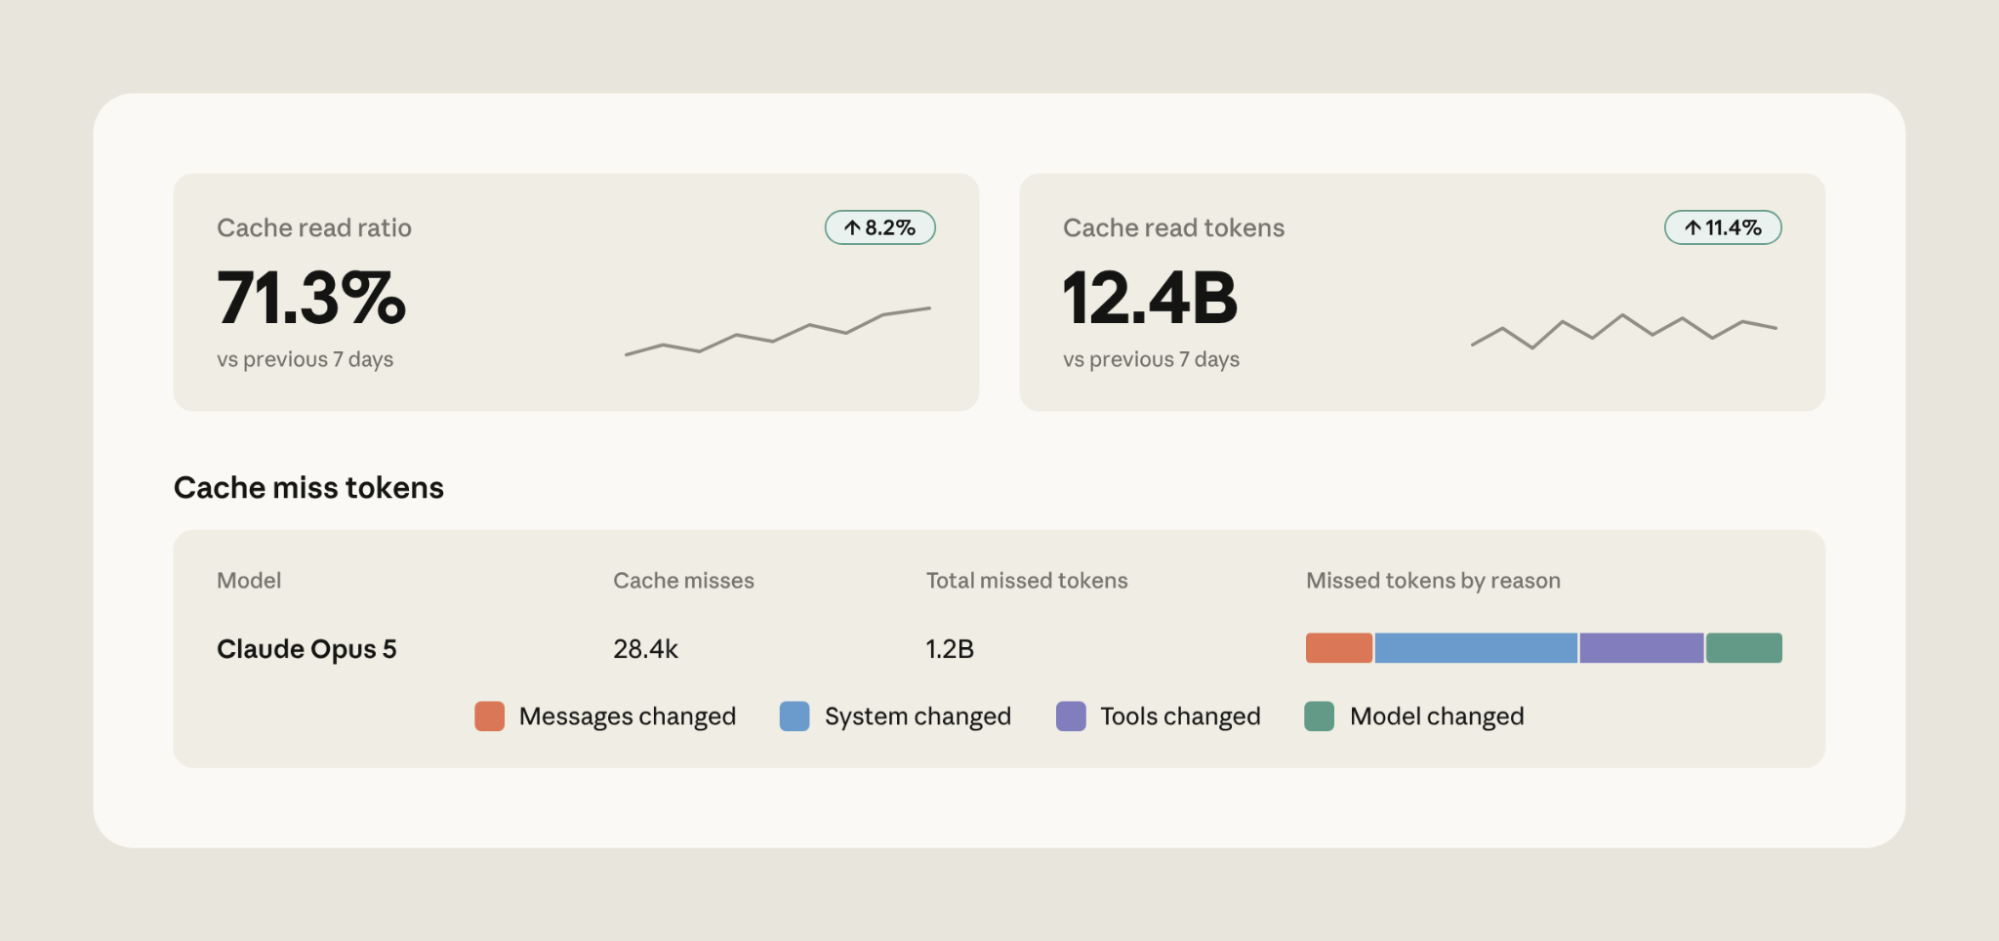
Monitor your prompt cache hit rate carefully . Claude Console:https://platform.claude.com/docs/en/build-with-claude/cache-diagnostics and the cache diagnostics API:https://platform.claude.com/docs/en/build-with-claude/cache-diagnostics provide prompt cache diagnostics, including reasons for prompt cache misses (Figure 1) and exactly where two requests diverged.
Prompts can accumulate instructions that patch model weaknesses. These instructions can drift relative to the capabilities of the latest Claude models:https://x.com/trq212/status/2080710971228918066. Here are common prompting “anti-patterns” that hobble frontier Claude models and can inadvertently increase costs:
We've updated the claude-api skill with a new command that watches out for these anti-patterns. In Claude Code, run /claude-api prompt-audit against your prompts, skills, or tool descriptions. The audit covers anything in your working directory, including application code that calls the Claude API and Claude Code's own configuration (e.g., CLAUDE.md:http://claude.md or skills).
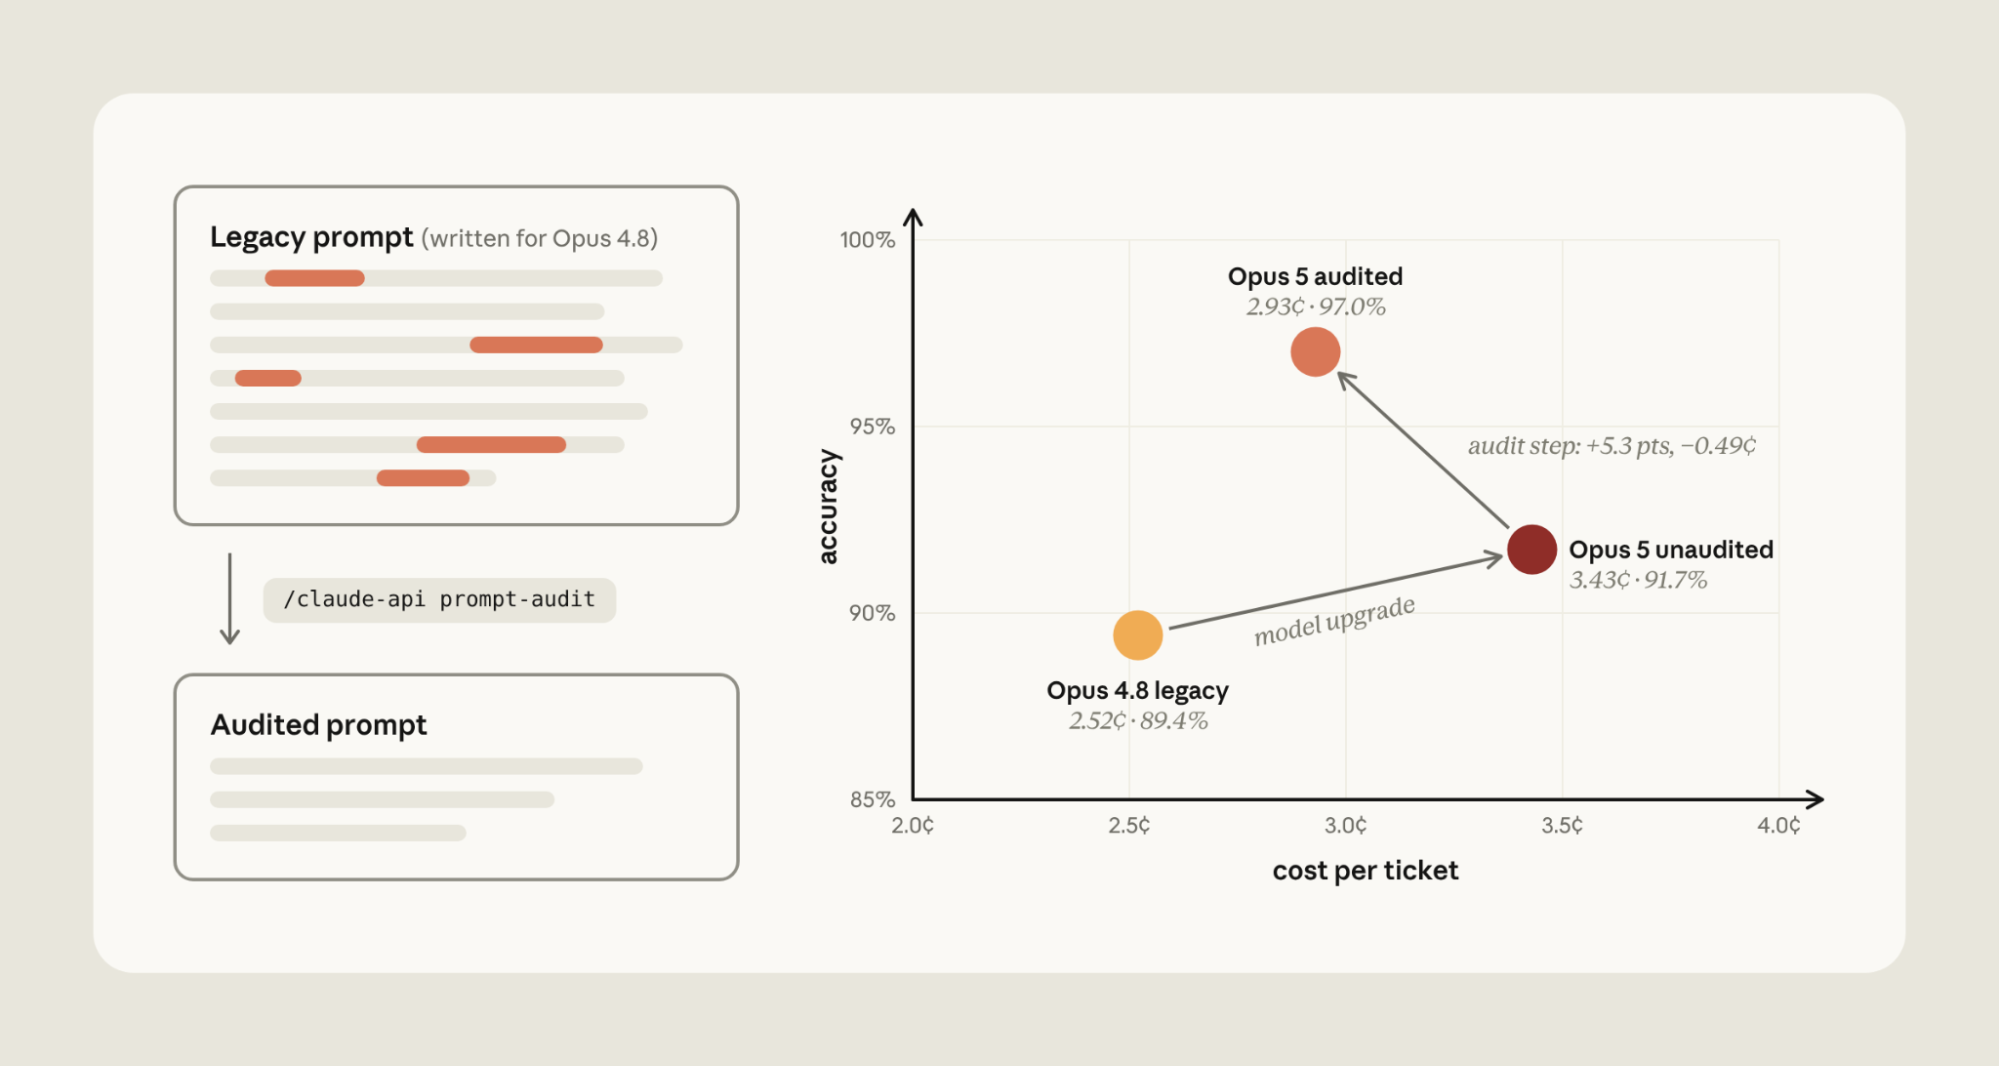
For example, we tested a model migration from Opus 4.8 to Opus 5 on a customer support benchmark. We started from a clean prompt and planted one anti-pattern at a time (a retired thinking setting, a pair of contradictory refund rules, a manual scratchpad, "verify twice", "be maximally thorough", and a mandatory six-step procedure), giving six legacy prompts.
We ran each on Opus 4.8, on Opus 5 with only the model ID changed, and on Opus 5 after running /claude-api prompt-audit once per prompt (Figure 3 shows the average across the six).
Figure 3 | The effect of prompting anti-patterns during model migration from Opus 4.8 to Opus 5.
With Opus 5, verification rituals (" verify twice ") use unnecessary tokens by duplicating order lookup on every refund. Emphasis boosters (" be maximally thorough ") became dozens of unneeded knowledge-base searches.
Running /claude-api prompt-audit removed the anti-patterns, decreasing costs by 14.6% and increasing accuracy by 5.3% on average. Cost dropped because extra tool calls and duplicated reasoning were eliminated. Accuracy rose for three reasons. The retired thinking setting made the API reject every routing request outright. The contradictory refund rules led Opus 5 to withhold four refunds it owed while it asked the customer to confirm. And the manual scratchpad collided with Opus 5's built-in thinking: on three tickets it wrote the tool call inside its reasoning and never executed it.
Effort:https://platform.claude.com/docs/en/build-with-claude/effort tells Claude “how hard to work.” At low effort Claude generally reaches conclusions faster. At high effort, Claude deliberates, verifies, and explores alternatives before answering.
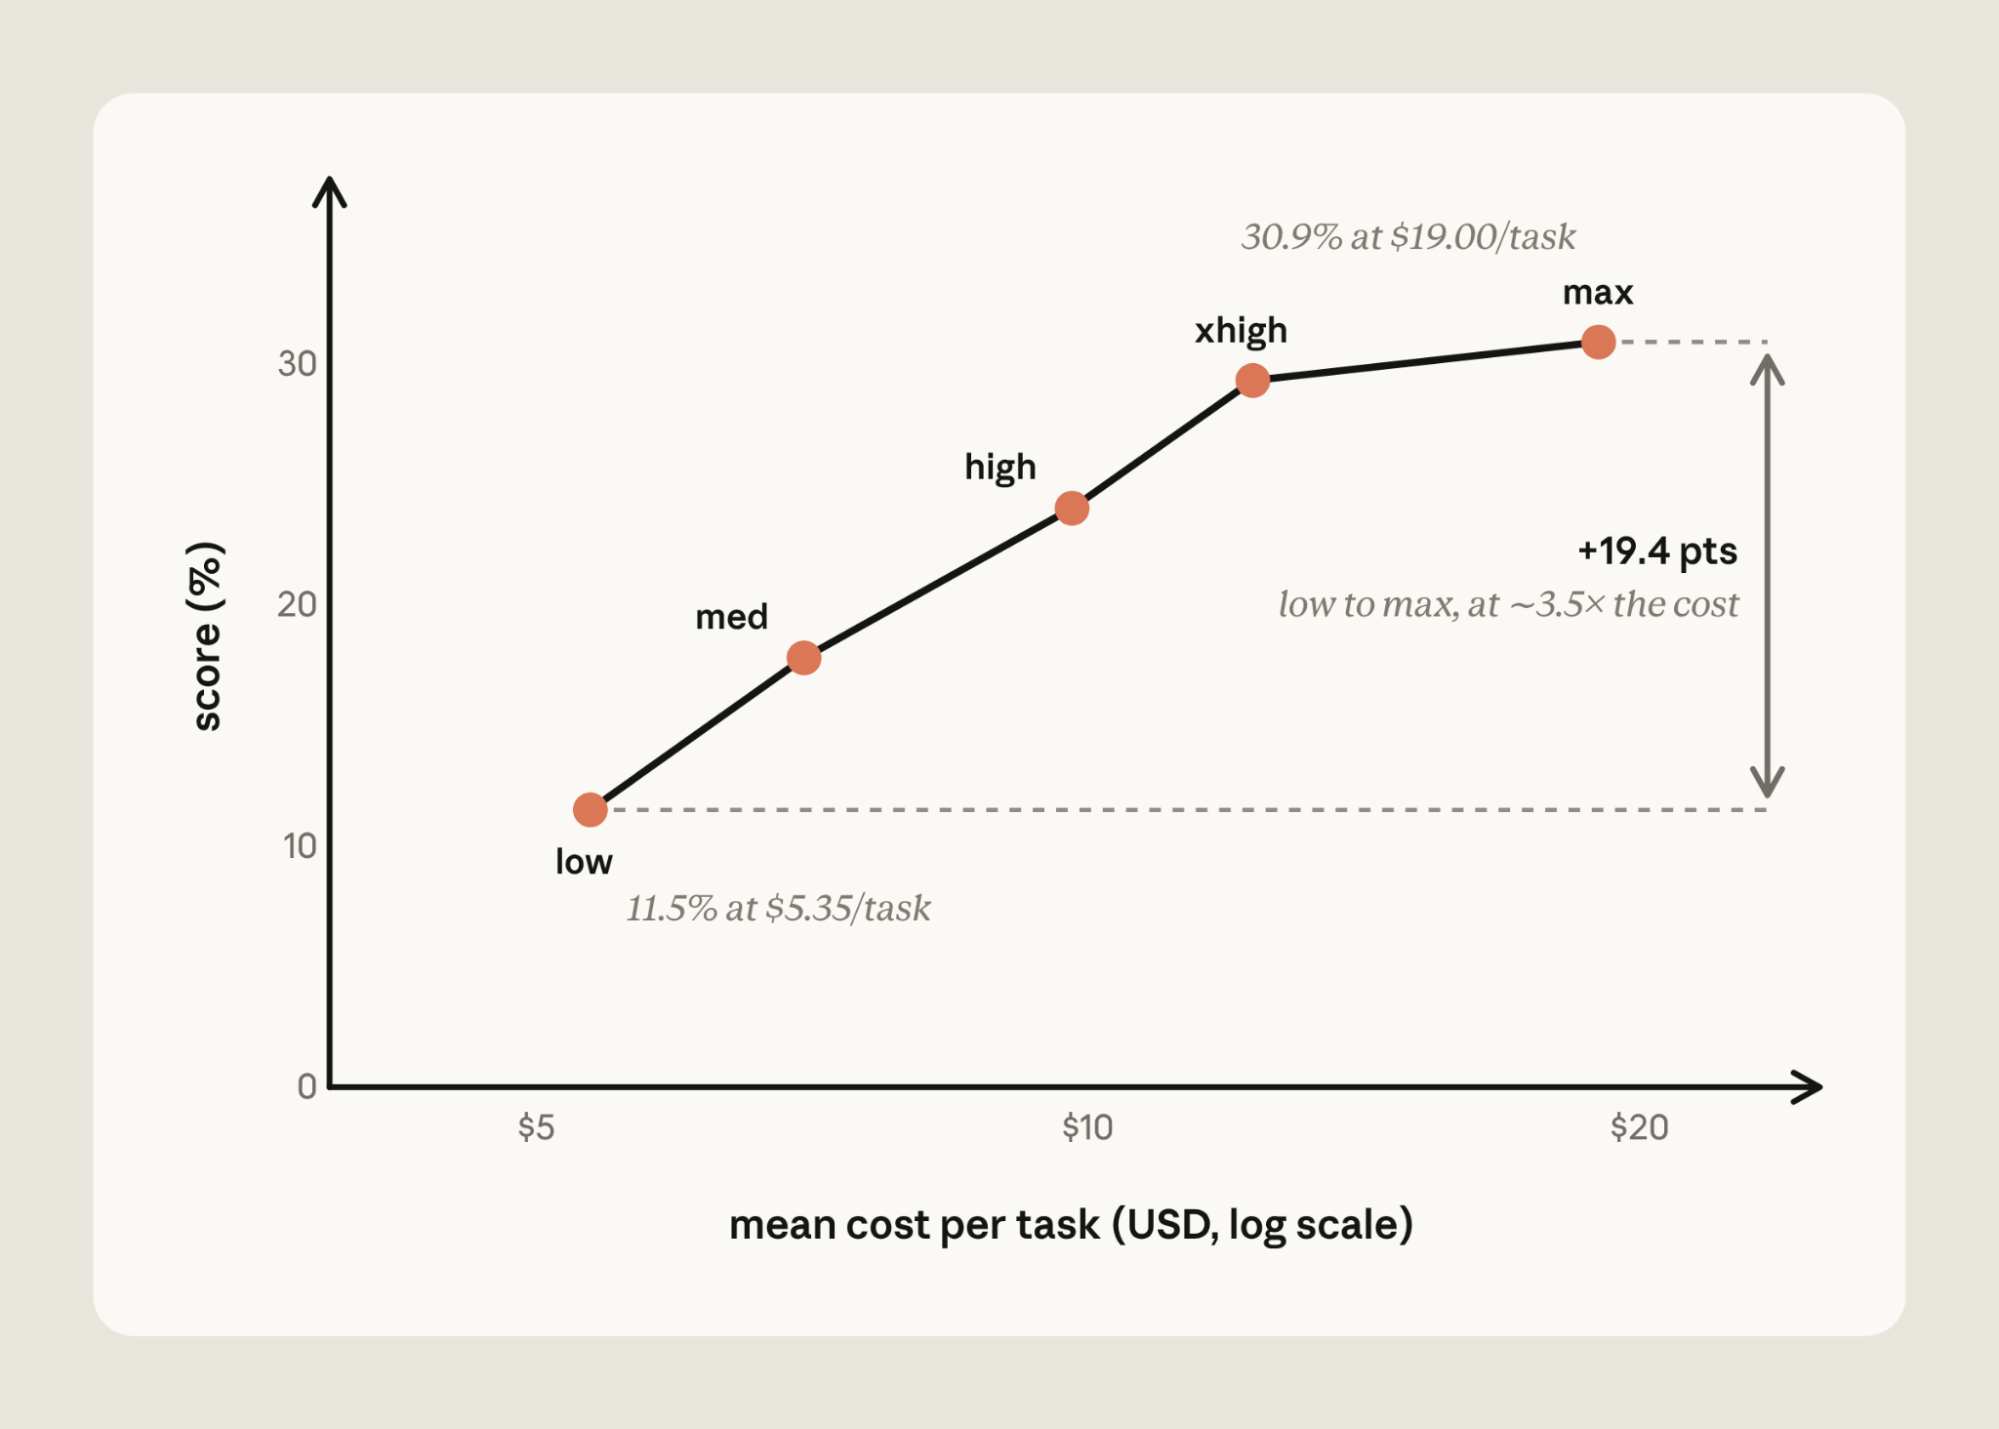
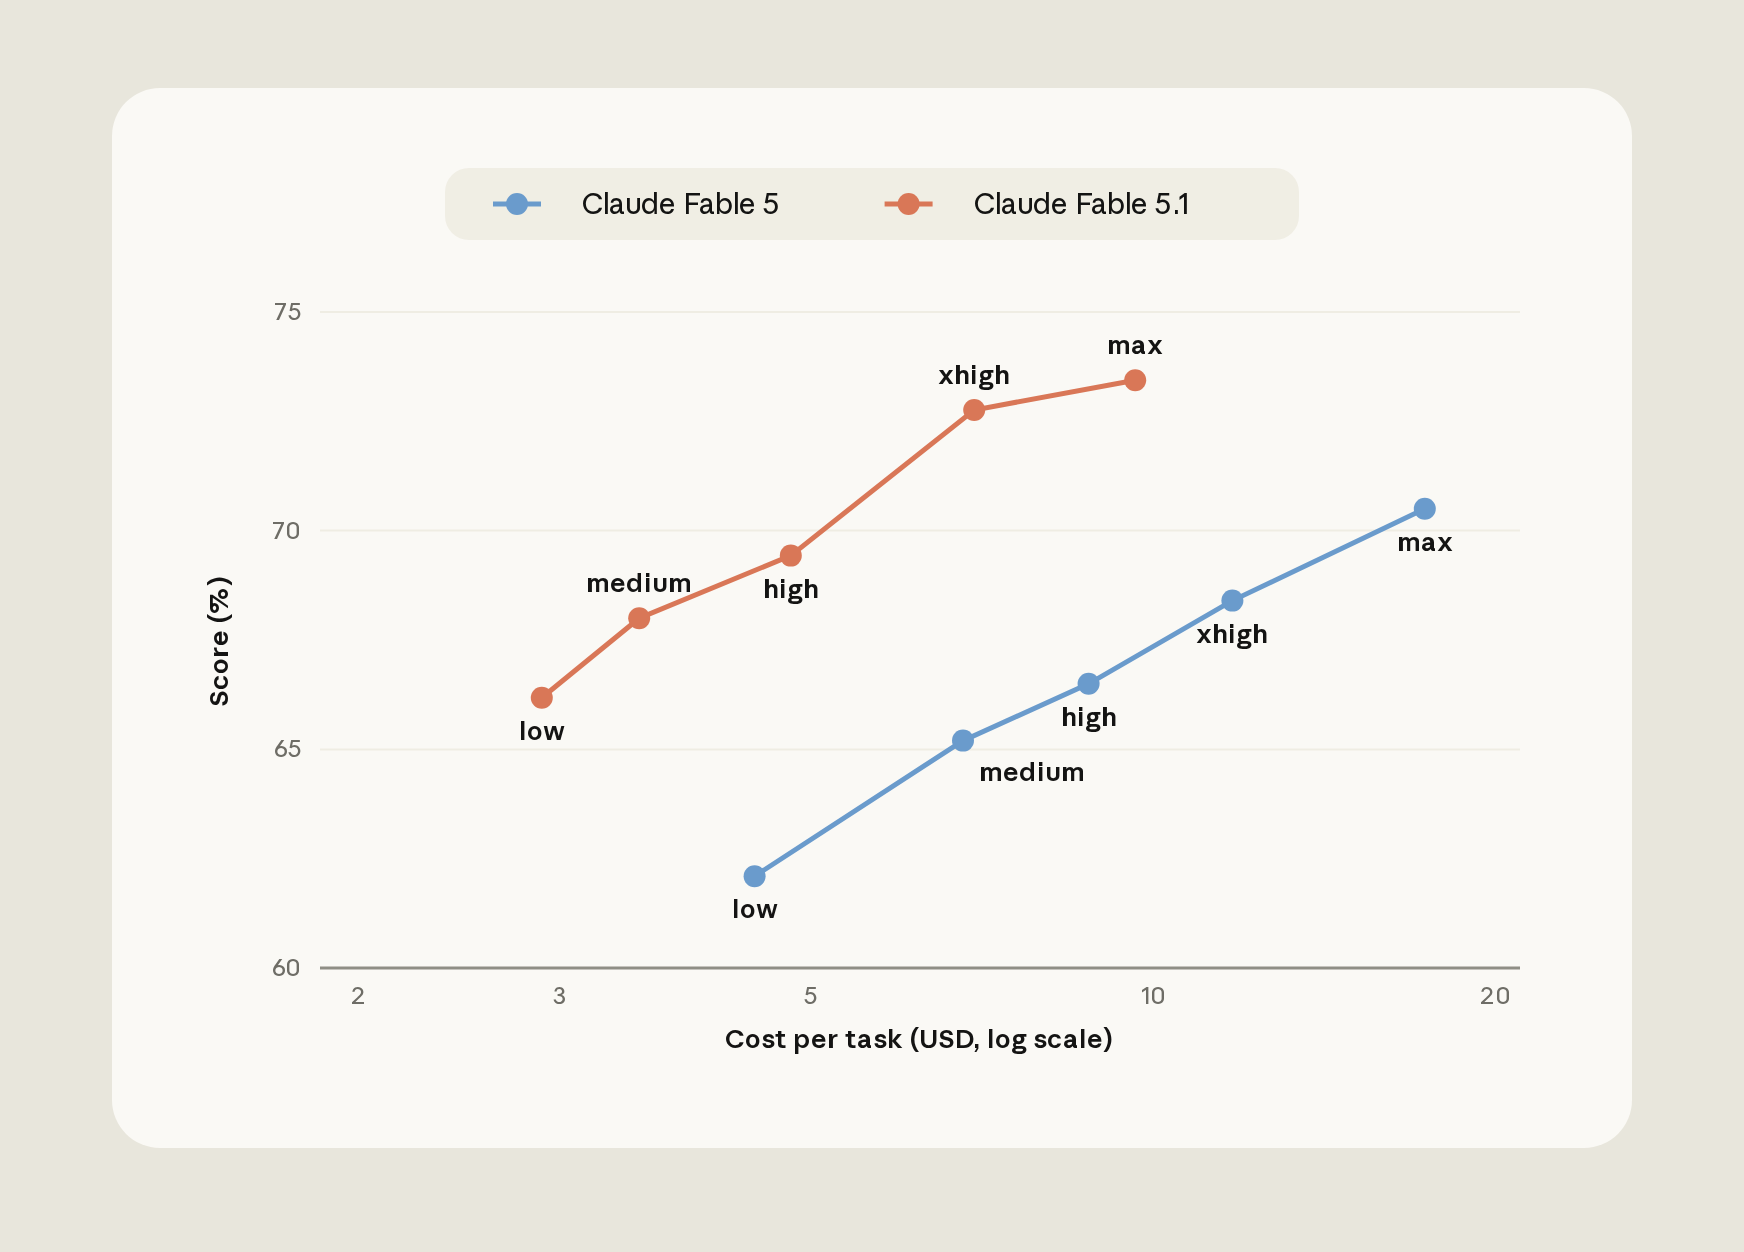
Cost-versus-performance across effort levels on a single model can vary. For example, Claude Fable 5 scores 11.5% at low effort for $5.35 per task on FrontierCode Diamond (the hardest 50 tasks). At max effort, Fable 5 gets 30.9% for $19.00 per task; changing effort raises the score about 2.7x (+19 points) for about 3.5x the cost (Figure 4).
On Claude Fable 5.1, Humanity's Last Exam (without tools) shows a steep curve with a diminishing last step. It scores about 53% at low effort for about $0.30 per question and about 61% at max effort for about $2.23; the last step up to max adds about half a point for 46% more cost. The gain falls inside the benchmark's run-to-run noise, so you pay more for no measurable gain.
Effort can be miscalibrated in either direction:
There are some useful ways to calibrate effort:
This calibration often involves running an evaluation across models and effort levels. In Claude Code, /claude-api hillclimb performs this search for you: it splits your evaluation into train and test sets, proposes configuration changes, and reads failing train examples to fix what it finds.
We ran it on a customer support benchmark, starting from Opus 4.8 at its default (high) effort. The hillclimber first tried Opus 5 at low effort, applying prompt-audit to remove mandatory tool-call rituals, scratchpad steps, and contradictory rules. That cleared the Opus 4.8 baseline at 98.9% train accuracy and cut cost to 2.6 cents per ticket.
It then stepped down to Sonnet 5 at low effort, which was cheaper still at 1 cent per ticket, but accuracy fell to 88.9%. Reading the failing train tickets, Claude added routing rules and a refund-cap cross-reference to the prompt, bringing Sonnet 5 back to 98.9% at the same cost.
On the 14 held-out tickets the search never saw, the final configuration scored 90.5% against the original setup's 78.6%, at about one fifth the cost.
Prompt caching, instructions, and effort are common levers for reducing cost. Our documentation:https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cut-spend-without-losing-quality covers even more. To run a holistic cost audit of application code that uses the Claude API, we've added /claude-api cost-optimize: it profiles where your spend goes, applies cost reductions, and, if you provide an evaluation, shows how savings trade off with performance.
cost-optimize starts by finding where your tokens go: from your organization's usage and cost reports:https://platform.claude.com/docs/en/manage-claude/usage-cost-api if you have a Claude Admin API key, from the usage object on each API response if your application logs it, or, failing both, by reading your request-building code and estimating.
It then ranks the available savings, starting with prompt caching, trimming what each request carries (including a prompt-audit), bounding output, and batching:https://platform.claude.com/docs/en/build-with-claude/batch-processing unattended work. If you supply an evaluation, it goes further and computes cost and performance across effort levels and model choices.
We ran this on four public benchmarks, starting with Sonnet 5 as a baseline (Figure 7):
Start with /claude-api prompt-audit when you've migrated to a frontier Claude model and want to check your existing prompts against it. It scans the prompts, skills, and tool descriptions in your working directory. This can be application code that calls the Claude API or Claude Code's configuration (CLAUDE.md, skills). It removes common anti-patterns that hobble frontier models.
Reach for /claude-api cost-optimize when your application uses the Claude API and you want a cost audit. It profiles token spend and then tests different levers: it applies prompt-audit, but also checks for ways to lower cost via prompt caching, batching unattended work, or bounding output. If you provide an evaluation, it measures the effort and model selection trade-offs.
Finally, use /claude-api hillclimb for an iterative search over cost and performance. Given an evaluation, Claude splits it into train and test sets, then proposes updates to your application that aim to reduce cost while maintaining baseline performance. Claude reads the failing train cases to guide the search, and the final configuration is scored on the held-out test set.
Explore more product news and best practices for teams building with Claude.
Product updates, how-tos, community spotlights, and more. Delivered monthly to your inbox.
情报判断
Aioga 编辑摘要
Anthropic 发布 Claude Platform 降本指南,并将相关指导纳入 claude-api 技能。文章提出三种方法:提高提示词缓存命中率、升级前沿模型时清除提示词反模式,以及按任务校准 effort。


 扫码直达文章详情