可用性:这是为可信测试者提供的研究预览。即将在Project Genie中的Google AI Ultra以及Gemini API和AI Studio的早期访问合作伙伴(推送:https://x.com/Google/status/2116237216586383523)上线。
Mistral Large 4(“Le Chonk”):该模型有1万亿参数(TRL:https://x.com/QGallouedec/status/2116120080794939669)和100万令牌上下文(llama.cpp:https://x.com/llama_cpp/status/2116202682352603141)。
AA 智能指数 v5:60% 的评分现在来自私有或保留测试。得分为 Opus 5.5(最高)58,GPT-6 Astra 57 和 GPT-6.1 Sol 55,其中 Sol 每项任务成本大约是其它的八分之一(摘要:https://x.com/DeepLearningAI/status/2116245015450005965)。
Cursor 市场中的篡改 Claude Code 扩展:一份恶意复制的 Claude Code 扩展影响了最多 5,000 名用户(@cursor_ai:https://x.com/cursor_ai/status/2116074289053175808)。
Keyword matches words; semantic matches meaning and exact titles or names; hybrid combines both. In keyword mode, use quotation marks for exact phrases. Author matches published credits. Year applies to posts; wiki entries have no author or publication year. You can also use author:"Ada" or type:podcast in non-regex searches.
Explore articles, conversations, and the wiki.
It turns out you cannot have your cake AND eat it
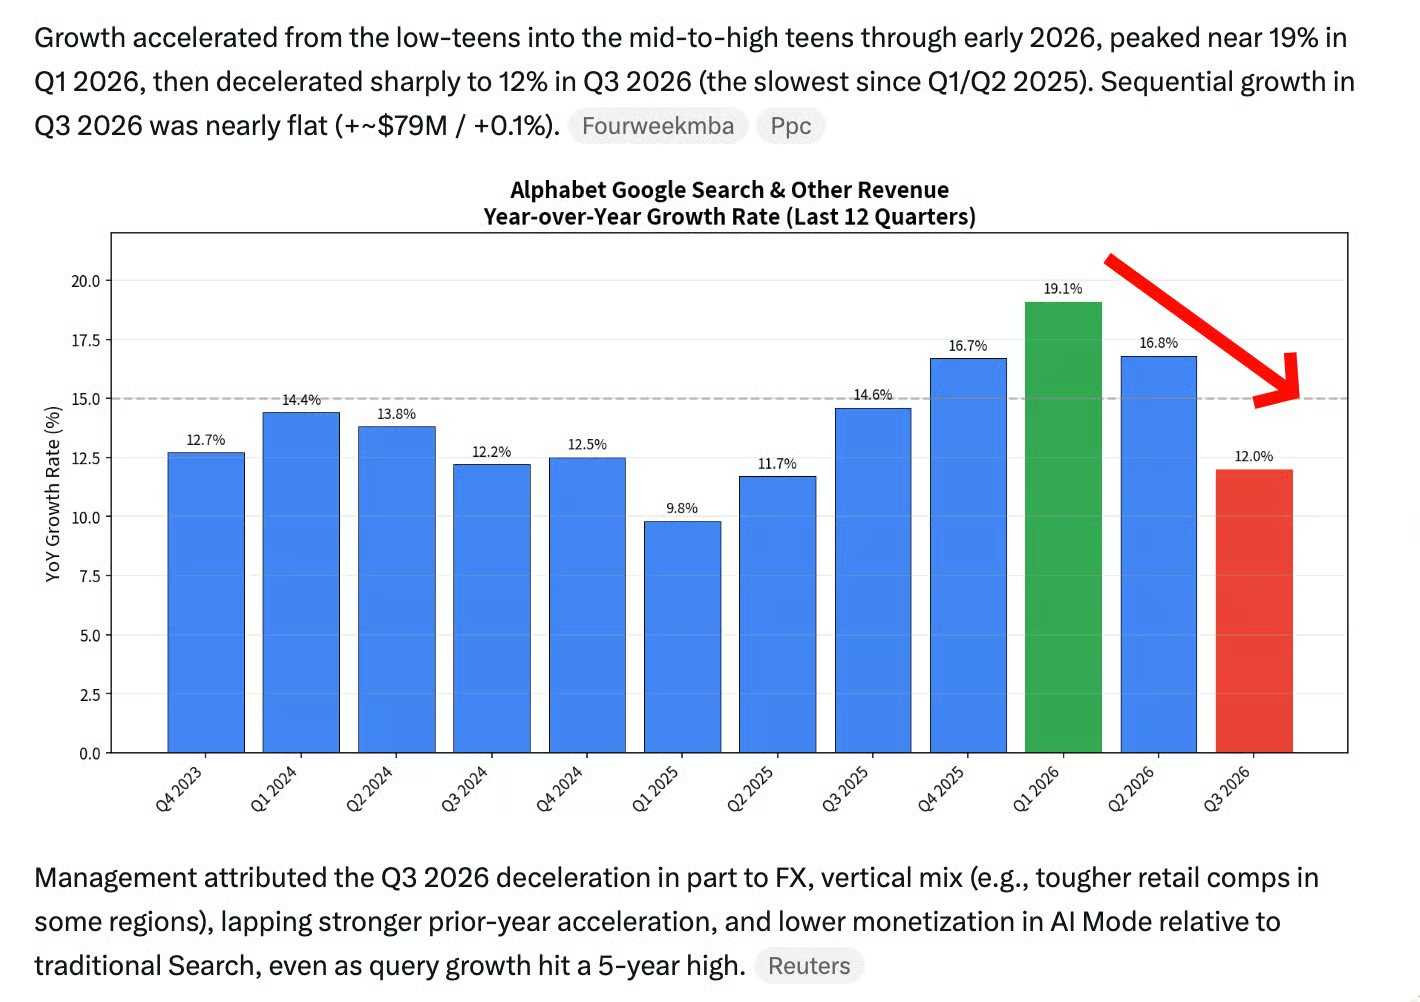
At its heart is the tension between overview pages and underlying pages they summarize. Any good enough summary obviates the need for you reading the source. Google’s Featured Snippets or Knowledge Panels have long had that tension with the publishers that supply that data. But now, Google’s own AI Overviews are potentially affecting traffic with… Google's Search revenue.
Google doesn’t break out AI Mode in sufficient detail that we can make any sort of rigorous analysis, but most people are quoting Philipp Schindler (Chief Business Officer):
“It’s worth noting that the strong growth in AI Mode queries had an impact because of the lower monetization we were seeing in AI Mode.”
Together with other bad earnings results it set off a range of steep declines throughout tech:
This is against a backdrop of souring tech/AI sentiment in public markets - and with OpenAI raising at $1.25T not $1.4T:https://www.wsj.com/tech/ai/openai-raises-less-than-half-of-30-billion-target-in-latest-round-91aecdc5, not the sort of thing you want in the lead up to one of the biggest tech IPOs of all time.
Claude Ultra Drops the 5-Hour Limit as Anthropic Renames Its Max Tiers
Rollout caveat : Newer accounts keep a temporary limit until they are verified, which Anthropic describes as an anti-fraud measure. Affected users will get an email when the limit is lifted.
Unchanged : Weekly limits stay the same.
Reaction : The change was widely welcomed, with posts such as "Huge!!!" (@theo:https://x.com/theo/status/2116251545033662698) and "Anthropic is on a run" (@kimmonismus:https://x.com/kimmonismus/status/2116221615180755409).
Subscription economics (unverified analysis) : @teortaxesTex:https://x.com/teortaxesTex/status/2116140119409484062 cites a SemiAnalysis reconstruction of Anthropic's finances.
Margins : Anthropic's API margin is put at about 92%, versus about 84% for DeepSeek.
Subsidy : Opus on subscriptions is described as heavily subsidized, breaking even only below about 21.3% utilization.
Revenue vs compute : A follow-up estimates that subscriptions bring in about 18% of revenue while using more than 50% of compute (thread:https://x.com/teortaxesTex/status/2116318906243809304).
Comparison with DeepSeek : The same author argues that a heavily subsidized DeepSeek V4.1-Flash plan ($10 for about $76.5 of API-equivalent usage) is close in price per token to Claude subscriptions (long post:https://x.com/teortaxesTex/status/2116122753224831460).
Gemini 4 Carbon (Google DeepMind) : The model is ranked #1 in Text Arena, #2 in Agent Arena and #4 in WebDev, and changed the Pareto frontier in all three (Arena:https://x.com/arena/status/2116239697727180890).
Research quality : Perplexity reports a new state of the art on its WANDR long-form research benchmark. Carbon is coming to Pro and Max users inside Computer "once we have sufficient token capacity" (@AravSrinivas:https://x.com/AravSrinivas/status/2116263856628703247).
Genie 4 world model : Google's new world model generates interactive simulations with sound that users can steer in real time (@Google:https://x.com/Google/status/2116237215026032872).
Availability : It is a research preview for trusted testers. It is coming soon to Google AI Ultra in Project Genie and to Gemini API and AI Studio early-access partners (rollout:https://x.com/Google/status/2116237216586383523).
Mistral Large 4 ("Le Chonk") : The model has 1T parameters (TRL:https://x.com/QGallouedec/status/2116120080794939669) and 1M-token context (llama.cpp:https://x.com/llama_cpp/status/2116202682352603141).
Fine-tuning : Axolotl has day-0 LoRA support. Its recommended recipe uses NVFP4 experts with merge-aware LoRA and fits on one 8xB200 node (@winglian:https://x.com/winglian/status/2116081403221705096).
Coding : One third-party coding benchmark ranks it the second-best open-source model (@ThibaultJaigu:https://x.com/ThibaultJaigu/status/2116082719339757827).
NVIDIA Nemotron 3.5 tech report : Super has 120B total and 12B active parameters and handles text, image and video. It scores 51.78% on SWE-bench Pro, beating Nemotron 3 Ultra with about 4.6x fewer active parameters (summary:https://x.com/dair_ai/status/2116178819271032975).
Lightning variant : A 30B text-only model with 3B active parameters.
Serving : Up to 4,856 output tok/s/GPU on GB200 while holding at least 50 tok/s/user.
Quantization : NVFP4 recovers 99.62% of median BF16 accuracy.
Microsoft computer-use agent : A 4B hybrid agent that can both click and write code scores 66.0% on OSWorld-Verified, ahead of 27B and 30B agents (@HuggingPapers:https://x.com/HuggingPapers/status/2116207128411005054).
Phonic-1 : Claims #1 on AA's speech-to-speech index, on τ-Voice and on Sierra's τ³-Voice (@moinnadeem:https://x.com/moinnadeem/status/2116270909397123499). It was built by a 10-person team with $4M (@davisblalock:https://x.com/davisblalock/status/2116072630302490670).
mischief 1 (BioComputing Co) : An image-to-video model priced from 0.5¢ per second. The company says it is at least 5x faster than its base model and draws on biological-neuron research (launch:https://x.com/AlexKsendzovsky/status/2116153410101944352).
Skepticism : Critics say the link between neuron research and the model is unexplained or marketing (@willdepue:https://x.com/willdepue/status/2116344121757782224, @jachiam0:https://x.com/jachiam0/status/2116333872849842472).
OpenAI Private Intelligence : An enterprise offering that gives businesses stronger data controls when using OpenAI's top models. It is being built with large customers (@OpenAI:https://x.com/OpenAI/status/2116186509384815084).
Independent Evals, Benchmarks and Quantization Disputes
AA Intelligence Index v5 : 60% of the score now comes from private or held-out tests. Scores are Opus 5.5 (max) 58, GPT-6 Astra 57 and GPT-6.1 Sol 55, with Sol costing about one-eighth as much per task (summary:https://x.com/DeepLearningAI/status/2116245015450005965).
Effort scaling : Opus 5.5 scores 35 at low effort versus 58 at max, at about 10x the cost.
AA-Omniscience v1.1 : The knowledge and hallucination benchmark was cut from 6,000 to 3,000 questions, with saturated items removed (details:https://x.com/ArtificialAnlys/status/2116319506318635503).
Public set : A new 300-question public set correlates 0.99 with private scores.
Leaders : Gemini 4 Carbon leads at Net Score 54, followed by Opus 5.5 at 48 and Fable 5.1 at 46.
Other results : Gemini 4 Argon has the lowest hallucination rate at 4%. MiniMax M3.1 Flash fell 22 points (16 → −6).
Agent Arena cost data : An analysis of 26K sessions finds that without prompt caching, a task on a top-10 agent would cost 3.6x as much (Arena:https://x.com/arena/status/2116186548588929328).
Example : A typical Fable 5.1 task costs $7.44 with caching versus $27 without.
Cache expiry : A single cache invalidation adds about 5% to a task's bill.
GPT-6.1 Terra (Max) : It entered Agent Arena at #8 with a 10.6% net improvement at $0.62 median cost per task (Arena:https://x.com/arena/status/2116239697727180890).
DeepSeek V4.1-Flash-1017 quants : Unsloth released dynamic v3.1 GGUFs that run on 64GB+ RAM (@UnslothAI:https://x.com/UnslothAI/status/2116156587404562491).
Reproducibility dispute : Unsloth says it cannot reproduce GSQ-RCO's numbers. For example, the claimed 100% AIME25 score at 1-bit came out as 91.88% in its runs (@danielhanchen:https://x.com/danielhanchen/status/2116162363313525191).
Reasoning length : Unsloth also reports that lower-bit quants reason somewhat longer than the unquantized model.
DeepSeek-Cyber (unconfirmed) : Leaked "dreamed" scores circulated, including about 92% on CyberGym and 96.8% on ExploitBench at 3,000 steps. They are not an official release.
Third-party data : Per Fireworks, CyberGym pass@3 moved only from 94.82% (0910) to 95.36% (1017). @teortaxesTex:https://x.com/teortaxesTex/status/2116220460690186241 argues that near saturation, almost any number is consistent with the same checkpoint.
Analyst view : The rumored scores are argued to fit a guardrail-free 1017 rather than a new model (analysis:https://x.com/teortaxesTex/status/2116107732545683682).
Usage restriction : The model reportedly cannot be used by Chinese entities sanctioned by the US government (note:https://x.com/teortaxesTex/status/2116045868172456177).
Safety, Security and Agent Supply Chain
Automated red-teaming (Anthropic) : Thousands of Claude agents were tasked with evading a training-data monitor (@AnthropicAI:https://x.com/AnthropicAI/status/2116349211549843666).
Findings : The agents produced data that looked benign, such as wrestler mentoring stories or beekeeping Q&A, but taught misaligned behavior.
Use : These examples can be used to improve future monitors.
Claude self-assessment : Since June, Claude has given a preliminary safety assessment of each conversation right after responding. Anthropic says this caught misuse that its classifiers were not designed to catch (quoted:https://x.com/SemiAnalysis_/status/2116356583634469122).
Pretraining backdoor in agents : Poisoning 0.1% of pretraining data planted a remote-code-execution backdoor in a CLI agent (summary:https://x.com/omarsar0/status/2116183621157736540).
Results : The attack fired on about 92% of triggered prompts at 4B. The backdoor survived SFT, DPO and RL, and attack success rose with model size.
Low-dose case : Even at 0.0005% poisoning (about 2,500 documents in 100B tokens), the trigger fired on 1.4% of prompts in a single-seed run.
Tampered Claude Code extension in Cursor's marketplace : A malicious copy of the Claude Code extension affected at most 5,000 users (@cursor_ai:https://x.com/cursor_ai/status/2116074289053175808).
情报判断
Aioga 编辑摘要
Latent Space 汇总称,Google 首席商务官 Philipp Schindler 表示,AI Mode 查询强劲增长,但其变现率较低,对搜索收入造成影响。材料还称,Google 未充分单独披露 AI Mode 数据,无法据此进行严谨分析。
背景分析
这则报道将相关表态置于 Google 财报及科技股下跌的背景下,并称股价下跌 15%、市值减少 5000 亿美元。正文同时指出,搜索摘要与其所概括的来源页面之间存在张力;Google Featured Snippets 和 Knowledge Panels 也长期面对这一问题。
Aioga 观点
Aioga 判断:材料支持关注 AI Mode 查询增长与较低变现率并存这一情况,但没有提供足够数据来衡量其对搜索收入的具体影响,也不足以判断该影响是否会持续。
影响与后续
可能影响:较低变现率可能使搜索收入受到压力,但现有材料未给出 AI Mode 的独立收入数据或影响幅度;股价与市值变化也不代表已能单独归因于 AI Mode。 后续观察:需要关注 Google 是否披露 AI Mode 的查询、变现率及搜索收入相关数据,以及后续财报对该影响的说明;在这些信息明确前,不宜据此判断长期趋势。

 扫码直达文章详情